Written by: Vector Podcast Team
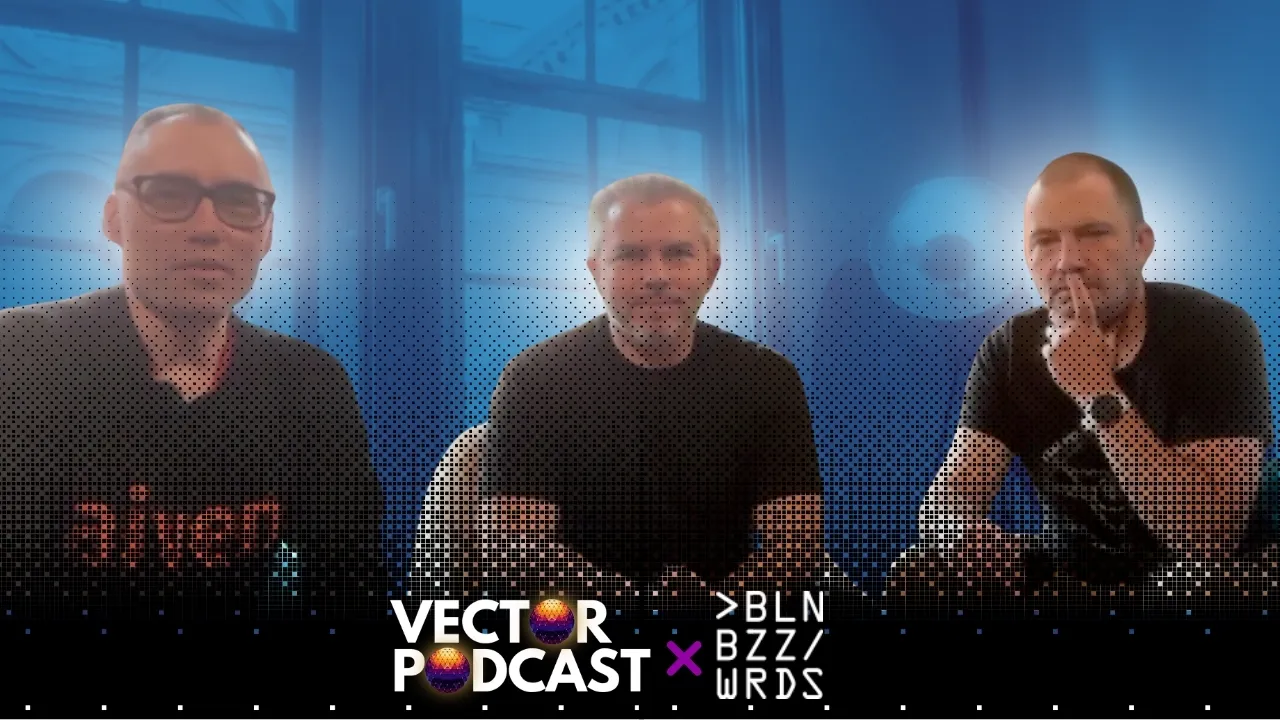
Doug Turnbull and Trey Grainger on search in the age of agents

Doug Turnbull, Trey Grainger and Dmitry Kan recording the Vector Podcast at Berlin Buzzwords 2026

Doug Turnbull and Trey Grainger are the authors of AI-Powered Search, and they teach the course version of the same title through Maven. They sit down with Dmitry to talk about what happens to retrieval when the primary user of a search engine is an LLM: why a search engine is still a cache, why chunking and embedding everything is the wrong first move, and where agentic search is starting to fragment.

Recorded on-site at Berlin Buzzwords 2026.

Doug Turnbull and Trey Grainger are the authors of “AI-Powered Search”. Between them they have led search teams for a couple of decades, and they teach the course version of the same title through Maven.

Search still matters, if anything more than before. ChatGPT became useful the day it got search. RAG is now the first step for most AI engineers, and the quality of an LLM answer sits directly on top of the retrieval underneath it. A search engine is a cache. Grepping through everything works at small scale but breaks down past roughly a hundred thousand documents.

A few things that come up:

  • The anti-pattern for teams with existing keyword search is to assume they must chunk and embed everything. A hundred million documents easily becomes ten billion vectors, and teams spend a year building that infrastructure without ever proving product value.
  • If your data is too big to vectorise cheaply, quantise. Single-bit-per-dimension representations index fast for a first pass, with full-fidelity vectors on disk for re-ranking. Hybrid keyword-and-vector search with reciprocal rank fusion is where most engagements start.
  • Coding agents have had a useful side effect. They force people to organise their content and leave breadcrumbs for discovery, which is what search teams have been asking clients to do for years.
  • Agentic search is fragmenting. Some teams give an agent basic tools like BM25 and let it loop until the results are good. Others invest in smarter retrieval like late interaction so the agent gets what it needs in one call. A smaller group is using reinforcement learning to fine-tune compact models for the search task.
  • Trey’s bet is on doing the agent work offline. Use LLMs at index time to enrich documents with taxonomy and attributes, and use semantic knowledge graphs at query time to interpret what the user meant. He expects the industry to swing back from “let the agent loop and burn tokens” once teams start pricing the latency and compute.
  • For vendors: keep building Lego pieces. The field is moving too fast for a packaged answer to stay right.

The course is called “AI-Powered Search: Modern Retrieval for Humans and Agents” and runs through Maven. Guest instructors this cohort include practitioners from Vespa and LightOn. More at aipoweredsearch.com.